
Introduction — a dark question
Have you ever wondered what happens when productivity meets a machine that seems almost too smart for our shifts? I watch shops lose hours to tiny missteps, and the numbers pile up like ash. A double spindle CNC machine sits at the heart of that pile in many plants—two spindles, one part program, yet yields and uptime tell a sad story. Recent shop-floor audits I’ve seen report as much as 18% lost cycle time due to poor tooling change and setup routines (yes, real data). So why do some teams get clean runs while others fight scrap every week? The scene feels bleak. Machines hum, lights blink, yet the output lags — and that tension keeps me up sometimes. Which is why I keep asking: what separates the high performers from the rest? — a small, stubborn question that leads us into the guts of the problem. Let’s move into the technical faults and the user pains that hide behind neat cycle charts.

Part 1 — Exposing the deeper layer: technical failures and user pain
cnc turning manufacturer is the name I keep hearing when shops talk about capability, but capability on paper does not equal reliability on the floor. I’ve seen controllers misroute spindle sync, tooling offsets drift, and bar feeders hiccup in the worst moments. The result? Missed tolerances and frustrated teams. The real faults tend to hide in the control logic and the human-machine handoff. Servo turret indexing errors, Y-axis backlash, and inconsistent chuck pressure are small problems on their own — but they cascade. Sensors report fine, yet the parts tell another story. Look, it’s simpler than you think: if a turret offset is out by a fraction, you lose fits, and then rework becomes the norm. (It’s maddening).
In technical terms, legacy fixtures and dated PLC sequences often fail to capture real-time feedback. Edge computing nodes are rarely used to pre-process spindle telemetry, and power converters can mask transient spikes that later show up as tool chatter. I prefer to break failures into two classes: deterministic faults (setup, program) and stochastic faults (wear, electrical noise). Most shops focus on the former; they tune g-code and tighten alarms. But wear and signal integrity slip under the radar. This mismatch creates invisible downtime — the kind you can’t bill for but that bites margins. I feel for operators; they see alarms and shrug, yet their hourlies suffer. Why? Because the system was not designed to share enough context at the right time — and that’s a design problem, not a people problem.
Why do control-level slips matter?
Because they turn predictable cycles into guesswork. When a spindle loses sync you don’t just scrap one part — you break the flow. And fixing it often means long waits and painful manual adjustments.
Part 2 — Looking forward: principles, tech paths, and metrics
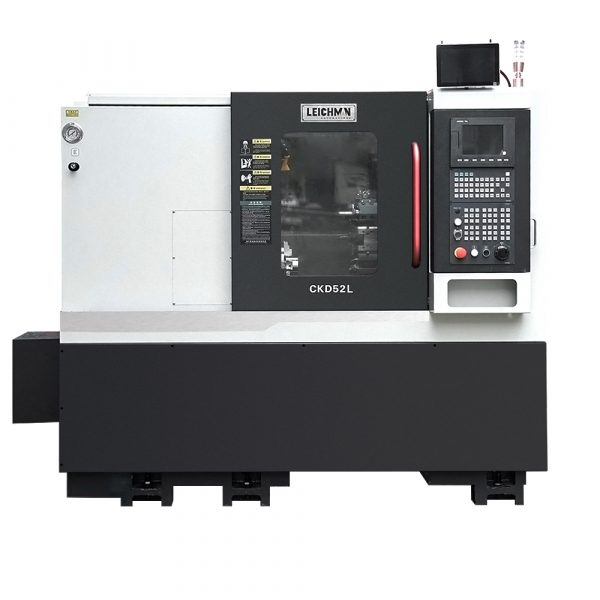
When I talk about the future, I imagine systems that give operators clear, honest signals before a hiccup becomes a crisis. A practical path uses smarter control logic, closed-loop feedback on both spindles, and better tool life tracking. That’s where a twin spindle lathe can really shine — not as a novelty, but as a platform for redundancy and parallel work. For example, pairing synchronized spindle motion with live tooling and integrated chucks reduces handoffs. It shortens non-cutting time. I’ve seen setups where cycle time fell by double digits once the control logic was reworked to prioritize spindle overlap instead of rigid sequencing. — funny how that works, right?
What should you evaluate? First, look for systems that expose spindle torque curves and vibration signatures in real time. Second, prefer controllers that let you simulate multi-spindle timing without stopping the line. Third, check for a robust tooling database with wear prediction. These three metrics — signal clarity, simulation capability, and tooling intelligence — separate vendors that sell bells and whistles from those that deliver uptime. I’ll be blunt: a flashy HMI is useless if the controller doesn’t tell you why a spindle drifted. The future is not just faster machines. It’s machines that tell you what’s wrong, early, in plain terms.
What’s Next?
Adopt smarter diagnostics. Start with one process and instrument it. Compare results. Scale only after you see real gains. You’ll learn faster that way than by chasing every new gadget.
Conclusion — measurable advice and final thoughts
I’ve worked with teams who feared change and with teams who embraced it. The winners are the ones who test metrics and hold systems accountable. So here are three practical evaluation metrics I use and recommend: 1) Mean time between adjustments — how many hours elapse before manual intervention? 2) Tool utilization rate tied to actual part output (not just hours run). 3) Multi-spindle synchronization error measured in microns over long runs. Use these numbers to judge claims. I’m honest about my bias: I trust data that points to clear fixes. You’ll get fewer surprises that way — and fewer late nights on the line. — the shop floor deserves that.
Finally, if you want a partner to explore these paths, check the product line at Leichman. I mention them because their platforms let you test the ideas I’ve described without ripping up your whole process. In the end, the machines are tools. We design the work. That human factor matters more than any feature list. I’m convinced of it. And yes, it’s personal — I’ve seen the difference.